Mateo
Full Stack Developer
ReactNode.jsPythonTypeScriptNext.jsMongoDBAWSAIAPIs
Resources
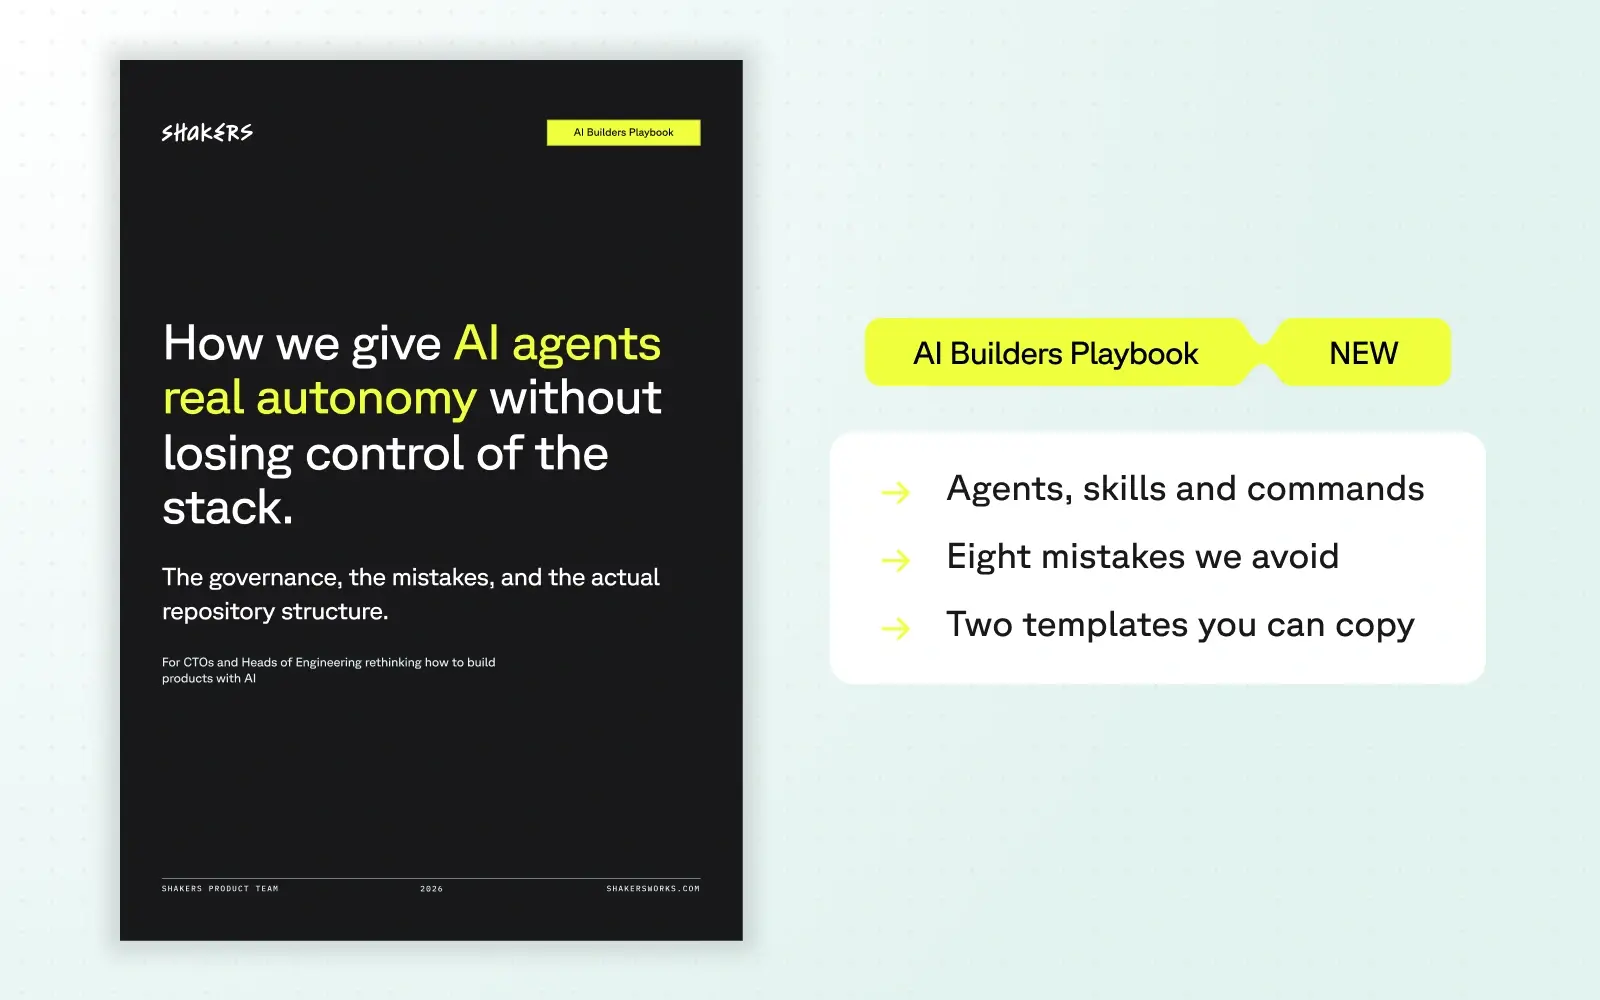
AI Builders Playbook
For CTOs and Heads of Engineering rethinking how to build products with AI.
Shakers for companies
A certified data engineer specialised in the Databricks platform: the lakehouse on Delta Lake that consolidates your data, Spark pipelines that scale without rewrites and a Unity Catalog that keeps access in order.
Senior tech talent on the workspace you already run, starting in days and budgeted by scope.




European clients across different industries
We work with the top 4% of certified talent in our community
Meet 3 certified candidates in under 72 h
Our clients' satisfaction on Trustpilot
The talent mix your company needs


A Databricks Engineer is a data engineer specialised in the Databricks platform: they build the lakehouse on Delta Lake, write the pipelines in Spark and PySpark and open the data to the business with Databricks SQL, all governed by Unity Catalog.
It is the data engineer specialisation for companies done with silos: batch and streaming, structured and unstructured data, on a single platform over AWS or Azure.
One provider. One contract. Full traceability
Tell us about the project, its scope, the expertise you need and when you want to get to work.
We match your brief against certified talent and introduce the three AI Builders who fit best.
Meet the three specialists and choose who you collaborate with; we handle the rest.
Why work with Shakers
Batch and streaming on Delta Lake: structured and unstructured data live on the same platform the business queries.
Transformations that survive data growth without rewrites: partitioning and jobs that hold when the spike arrives.
Who accesses which table, with what permission and with data lineage: the governance that keeps the lakehouse in order as it grows.
The business queries with standard SQL over the same data the pipelines serve: one figure for finance, operations and product.
Autoscaling and cluster policies designed before the first invoice: the platform sustains itself when the project ends.
MLflow and governed data leave the path ready for models: when the scientist arrives, they do not start from zero.
Any other questions? Our team will answer them.
Tell us your data projectAn orderly workspace: bronze, silver and gold zones on Delta Lake, the first production pipeline and a catalog with permissions per team. Every table has an owner, a cadence and lineage.
2,347 active tech job postings in the UK ask for Databricks, according to Shakers market analysis (n=56,780, October 2026). It is no longer a CV extra: it appears in MLOps, senior data science and AWS data engineering briefs.
They build and govern the data platform; interpretation belongs to the analyst and the model to the scientist. If your problem is deciding which chart to look at, a different role fits.
A badly partitioned job does not fail in the demo: it fails when the data grows and the invoice lands. Scope and cluster size are agreed before kickoff.
Connect with AI specialists to build your next project
The general craft this role specialises: if the brief has no platform yet, start here and choose the workspace later.
Trains models over the governed data of the lakehouse: without reliable layers, the prediction goes nowhere.
Puts those models in production with MLflow on the same platform: the natural bridge once the data is home.
The account and network where the workspace runs: without that base solved, the cluster pays the toll on every invoice.
We introduce you to three ready_to_build AI Builders in 72 hours.
 English
✓
At Shakers, we use AI to represent some of our AI Builders, thereby protecting their privacy.